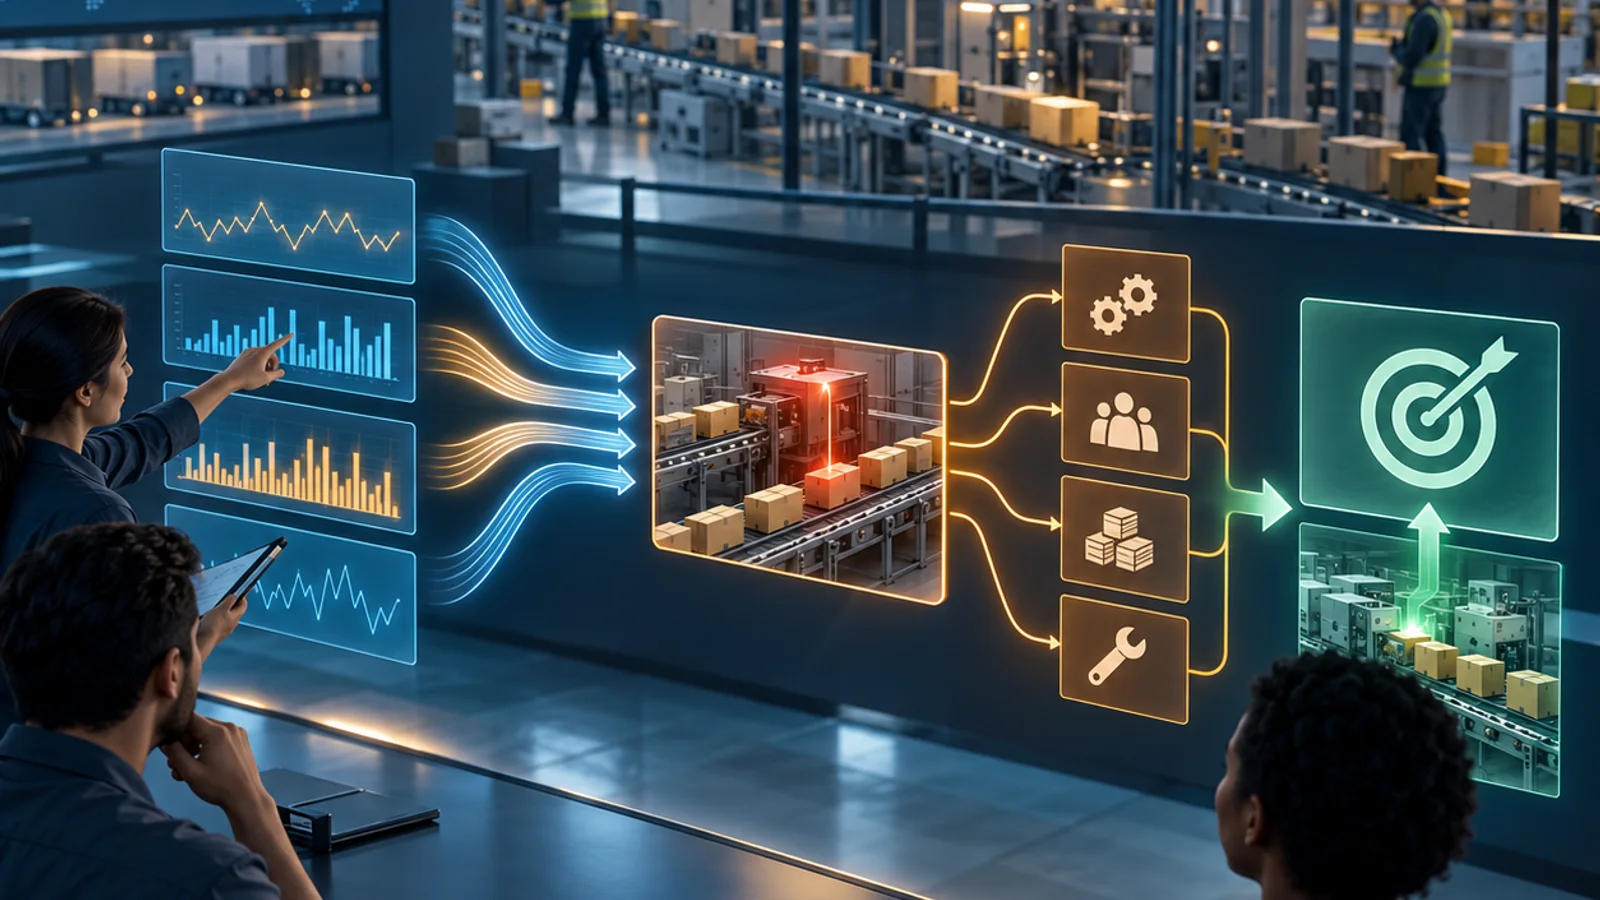
A dashboard may show more completed transactions while customers complain about delays. Both can be true: demand may have grown faster than output, or difficult cases may remain open. Operational performance analysis helps explain this picture. It starts by defining measures, tracing work and testing causes, then moves to improvements whose effects can be checked.
Turn a complaint into a question you can investigate
Operational performance analysis examines how a process produces its results and what explains the gap between required and actual performance. Replace “the team is slow” with a specific question: why were service requests due this week not completed on time? This identifies the outcome, period and population to investigate without assuming the cause.
Choose a Key Performance Indicator (KPI) linked to a clear objective. On-time completion may be more useful than transaction count alone. Pair it with a quality measure, such as the proportion returned for correction, so that speed does not improve at the expense of accuracy. An indicator should support a decision, rather than merely add a coloured number to a report.
Agree definitions before comparing numbers
To establish a baseline, define the measurement’s start and end points, unit, source and exclusions. Does service time begin when a request arrives or when its information is complete? Does the clock stop while waiting for the customer? Different perspectives can be useful, but do not combine them under one label. Keep total customer journey time alongside internal processing time when both matter.
Check missing and duplicate records, timestamps and reasons for corrections. Reconcile a sample against actual transactions and state the data’s limitations. When cases have no closing time, do not automatically treat their duration as zero. A completed-case report may exclude the most delayed cases. Monitor the age and due dates of open requests as well.
Separate the groups an average can hide
Average service time may improve because the team completes more simple requests while complex ones remain delayed. Compare results by request type, channel or shift, taking each group’s size into account. Do not compare a team handling complex cases with one handling routine cases and immediately attribute the difference to employee effort.
Show the distribution of times alongside the average. The median identifies the middle value in ordered data; the 90th percentile can help describe the slower end of service. Explain the calculation method, especially for small samples, and avoid firm conclusions from a handful of cases. Examine the time sequence too: a sudden increase raises a different question from persistent, stable delay.
Trace waiting before adding resources
Distinguish touch time, when work is actively performed, from total elapsed time. If a transaction takes 180 minutes and active work accounts for 20 minutes, the remaining duration is 160 minutes. Investigate how this is divided between waiting, handoffs, transport or pauses. Do not label all of it removable waste before understanding what happens during that time.
Compare incoming demand with throughput: the number of units completed in a defined period. Examine capacity actually available after downtime and other duties. A bottleneck is the constraint limiting process flow under current conditions. It might be a centralized approval or missing information, rather than the employee with the longest visible list. Trace transactions to understand the waiting before proposing recruitment or automation.
Hypothetical example: output increased, but so did the backlog
Suppose a service unit starts the day with 80 open requests, receives 120 and closes 100. Assuming no cancellations or reopened cases, its closing balance is 100 requests: 80 + 120 − 100 = 100. Completing more work than on a previous day is not enough to demonstrate improvement. Here, the backlog increased by 20 requests.
To measure on-time performance, suppose 100 requests were due during the week and 82 were completed by their deadlines. The result is 82%. The denominator includes every request due within scope, including overdue requests still open. Calculating the percentage from closed requests alone may conceal unfinished work. These are illustrative assumptions, not client results or universal performance benchmarks.
Transaction review shows that many requests wait for approval after processing is complete. Approval delay becomes a hypothesis worth testing. Examine sending, receipt and approval times, approver availability and reasons for returning requests. A queue before approval does not establish it as the only cause: work might arrive incomplete or in large batches.
Test a cause instead of simply naming it
Root Cause Analysis (RCA) helps explain a problem and select an appropriate response. A fishbone diagram organizes possible causes, while a Pareto chart ranks categories by a defined frequency or impact. These tools organize the investigation. An idea does not become a fact simply because the team agrees to place it on a diagram.
For each hypothesis, state what you would expect to observe if it were correct and what evidence would test it. In the approval example, trial a backup approver within authorized limits and compare waiting times for similar cases before and after the trial. Track changes in demand, complexity and any simultaneous adjustments. Improvement supports the hypothesis to the extent that the test is sound; it does not automatically rule out other causes.
When suitable sequential data is available, control charts help monitor variation over time. NIST’s handbook explains their use of statistical limits and patterns that warrant investigation. Do not confuse control limits with service targets or customer acceptance limits. A process can be statistically stable yet fail to deliver the required service. Chart selection and interpretation must reflect the data type and collection method.
Judge improvement through time, quality and cost together
Assign an action owner, review date, success criteria and conditions for stopping or changing the trial. If on-time performance rises from 82% to 90% in an appropriate comparison period, the increase is 8 percentage points. Examine approval errors, rework and complaints alongside it rather than declaring success from the speed measure alone.
For cost, distinguish released working hours from realized financial savings. Saving an hour of an employee’s time does not automatically reduce payroll. The benefit might instead be capacity for additional service. Record the calculation method and avoid counting the same benefit once as lower cost and again as additional production without explaining the relationship.
What if the data is insufficient?
Start by observing a limited number of cases and collecting the information needed to answer the specific question. Label the findings preliminary and identify what is missing. Do not replace missing records with invented numbers, or wait for a perfect system before beginning a disciplined investigation. Improving the measurement method itself may be the first necessary change.
Move from a red indicator to a clear decision
Choose one operational problem, establish its definition and check data quality. Trace delayed and completed cases, then test an explanation that evidence can support or reject. After the change, monitor results for a period appropriate to workload and variability. Complete the analysis cycle with a documented decision to continue or adjust, checking that improvement persists and the problem has not moved to another stage.